A data layer for people and AI agents
Stop filtering the news by hand.
Name a topic. feedql builds the feed.
feedql collects from the sources you choose, an LLM scores every item against your topic and says why, duplicates fold away and reports of one event are grouped. Your agents query it through MCP and the API; you read it on the web or export it for analysis.
No spam, one email when your seat is ready.
- 94Compact tokamak reaches a new plasma-confinement record 11 items grouped · first seen on GitHub · 2h ago Why: an experimental result, the core of your topic
- 86Open-source plasma simulator ships a major release 5 items grouped · first seen on Hacker News · 1d ago Why: a release of a tool you follow
- 78Funding round announced for a fusion start-up 3 items grouped · first seen on Hacker News · 3d ago
feedql = feed + query language.
Ask your feeds like a database. Filter by topic, source, time and score, and get grouped events back instead of a stream to scroll.
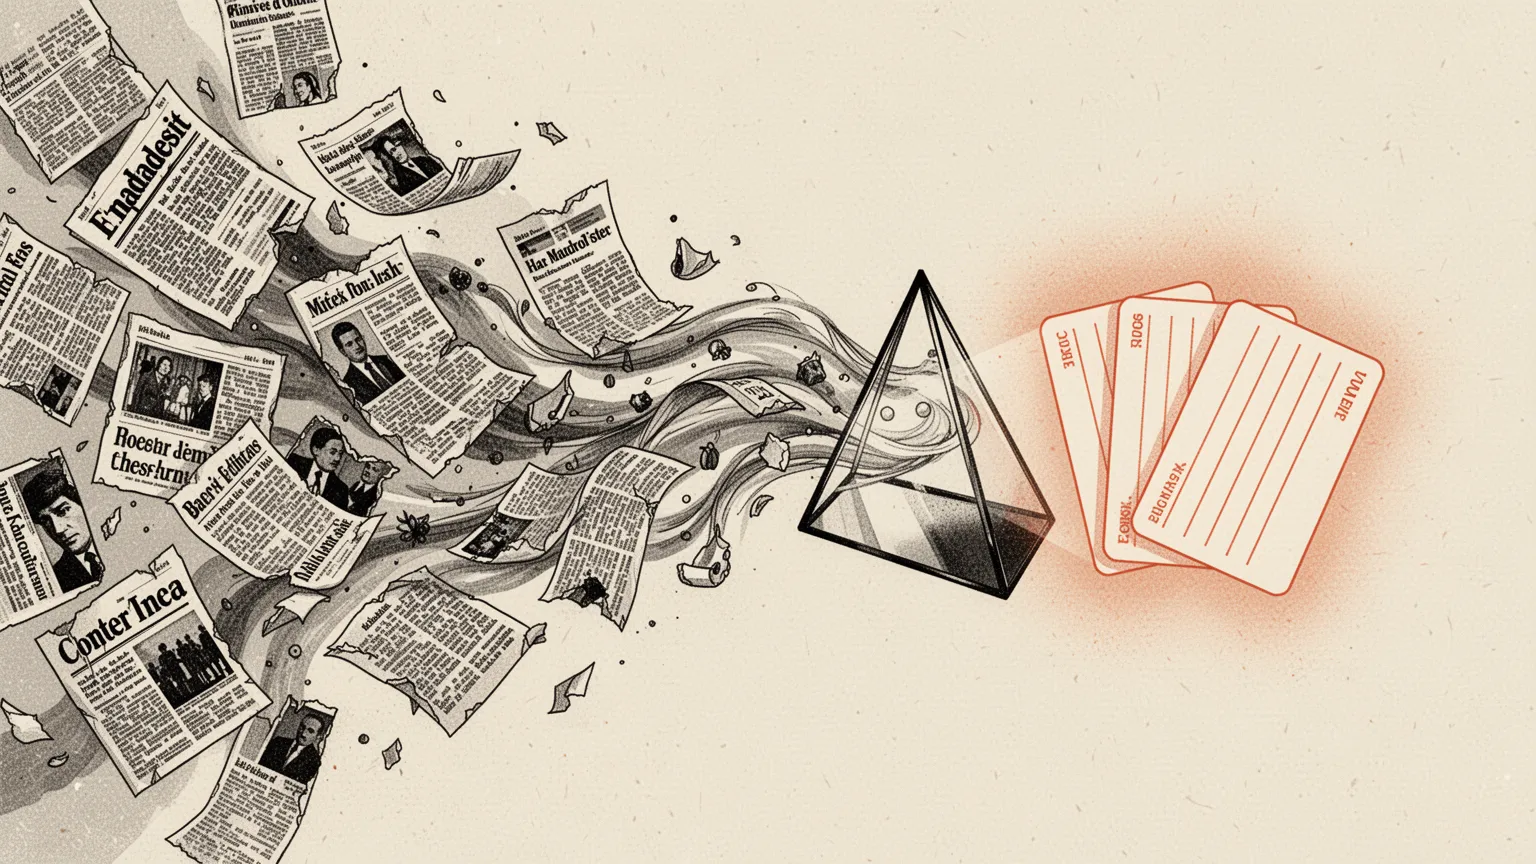
What we all tried.
- Alerts & RSS
A flood with no sorting
One story arrives five times because five sites reprinted it, and nothing tells you which copy came first.
- Big aggregators
Fine until the pivot
The product is rewritten for enterprise, features vanish, the API closes, and years of setup stay inside. Google Reader gave millions of people three months to leave.
- Fifteen tabs
Every morning, by hand
It works the longest, and it costs the most: the same sites, the same scrolling, the same things missed.
A feed that builds itself.
It started as a script for one person: pull HN, Reddit and GitHub, let a model decide what fits, and make it explain why. Two months later it reads 20+ kinds of sources.
Name a topic
Describe it in plain words. feedql finds where it is discussed, then you add the exact sites, repos, channels and people you already follow.
Duplicates fold away
Reprints and reposts of one story collapse into one entry instead of five.
One event, many sources
Posts, issues, reviews and filings about the same thing are grouped, with the first source linked.
Every item says why
Each score comes with a reason tied to your topic. A score without an explanation is not worth trusting.
One pool, two readers.
You need to see what matters fast and not get lost. Your agent needs structure. feedql serves both from the same data, and can be your agent's outside memory: say it researches a client, feedql has been collecting reviews of their apps for months, and the agent takes a clean base. No storage to run, nothing to rebuild from scratch.
MCP first
Connect Claude or your own agent in a minute: 60+ MCP tools to read, search and manage feeds. REST and webhooks for everything else.
Search the history by meaning
What feedql collected stays. Your agent finds past events by meaning, not only by keyword.
Structure, not a stream
Every record carries its source, score, reason and the event it belongs to.
Your data, exportable
Export everything as JSONL or CSV at any time. Nothing you set up is locked in.
Data ready for analysis.
Market research, competitor watch, app-review mining, lead and tender tracking: feedql does the collecting and cleaning, so your analysis and your LLM start from a dataset, not a scraper.
Months of clean history
Reviews, issues, posts and filings collected every day, deduplicated and kept as long as you need.
Scored and explained
Every record carries the LLM score, its reason, the source and the event it belongs to: ready for analysis, not just for reading.
Entity graph and SPARQL
Companies, products, people and tools linked across sources. Query the graph or walk it from your agent.
Export anywhere
JSONL or CSV into your notebook, warehouse or RAG pipeline. Semantic search over the same data through the API.
Ask the feed.
A built-in assistant sits next to every item. It answers from your actual settings and data, and it changes nothing without your confirmation.
- In beta
Why am I seeing this?
Answered from your real settings and data: which topic, which words, which source. Not made up.
- In beta
Find similar, sum up the event
Related items, a short summary of everything said about one event, and who the source is.
- In beta
Set up a topic by talking
Say what you want to follow; the assistant proposes the topic, sources and filters.
- Coming next
Is this worth my attention?
Clickbait or tabloid? How plausible is it? A second opinion before you spend the time.
- Coming next
Armchair expert
Talk the news through with someone who has read all of it.
Sources beyond RSS
- Hacker Newsnews
- Redditnews
- GitHubcode
- Xpeople
- Any site or blognews
- Mediumwriting
- YouTubevideo
- Telegramchannels
- Discourse forumscommunity
- Stack Exchangecommunity
- Web searchdiscovery
- App Store & Google Playreviews
- App releasesversions
- Product launcheslaunches
- Federal Registerlaw
- Grants.govfunding
- EU TED & Prozorrotenders
- LinkedIn & job boardshiring
Rolling out calmly.
Reading thousands of sources a day without getting banned, losing anything or flooding people with repeats is its own engineering problem. So feedql opens in steps.
Now
Private beta. The collection runs every day across thousands of sources.
Next week
The first small group from the waitlist gets in.
Then
Entry by invite, step by step, so nothing breaks and nobody gets flooded.
Join the waitlist
The first seats go to a small group. Leave your email and tell us what you follow.